Data Profiling in PySpark, Understanding Your Dataset Before Processing
Why looking at your data properly before writing any transformation logic matters, and the practical PySpark techniques for actually understanding a new dataset before building a pipeline around it.
Why this step gets skipped, and why that is a mistake
It is tempting, especially when you are under time pressure, to jump straight into writing transformation logic the moment a new dataset lands in your Bronze layer. You already know roughly what the data should look like based on the source system documentation, so why waste time actually looking at it first.
The honest answer is that documentation and reality do not always match, and the gap between them is exactly where pipelines quietly break later. A column that is documented as never null might actually have nulls in five percent of rows. A field described as always containing a two letter country code might occasionally contain a full country name because of an upstream bug that nobody has fixed yet. Data profiling is the step where you find these things out before they surprise you in production.
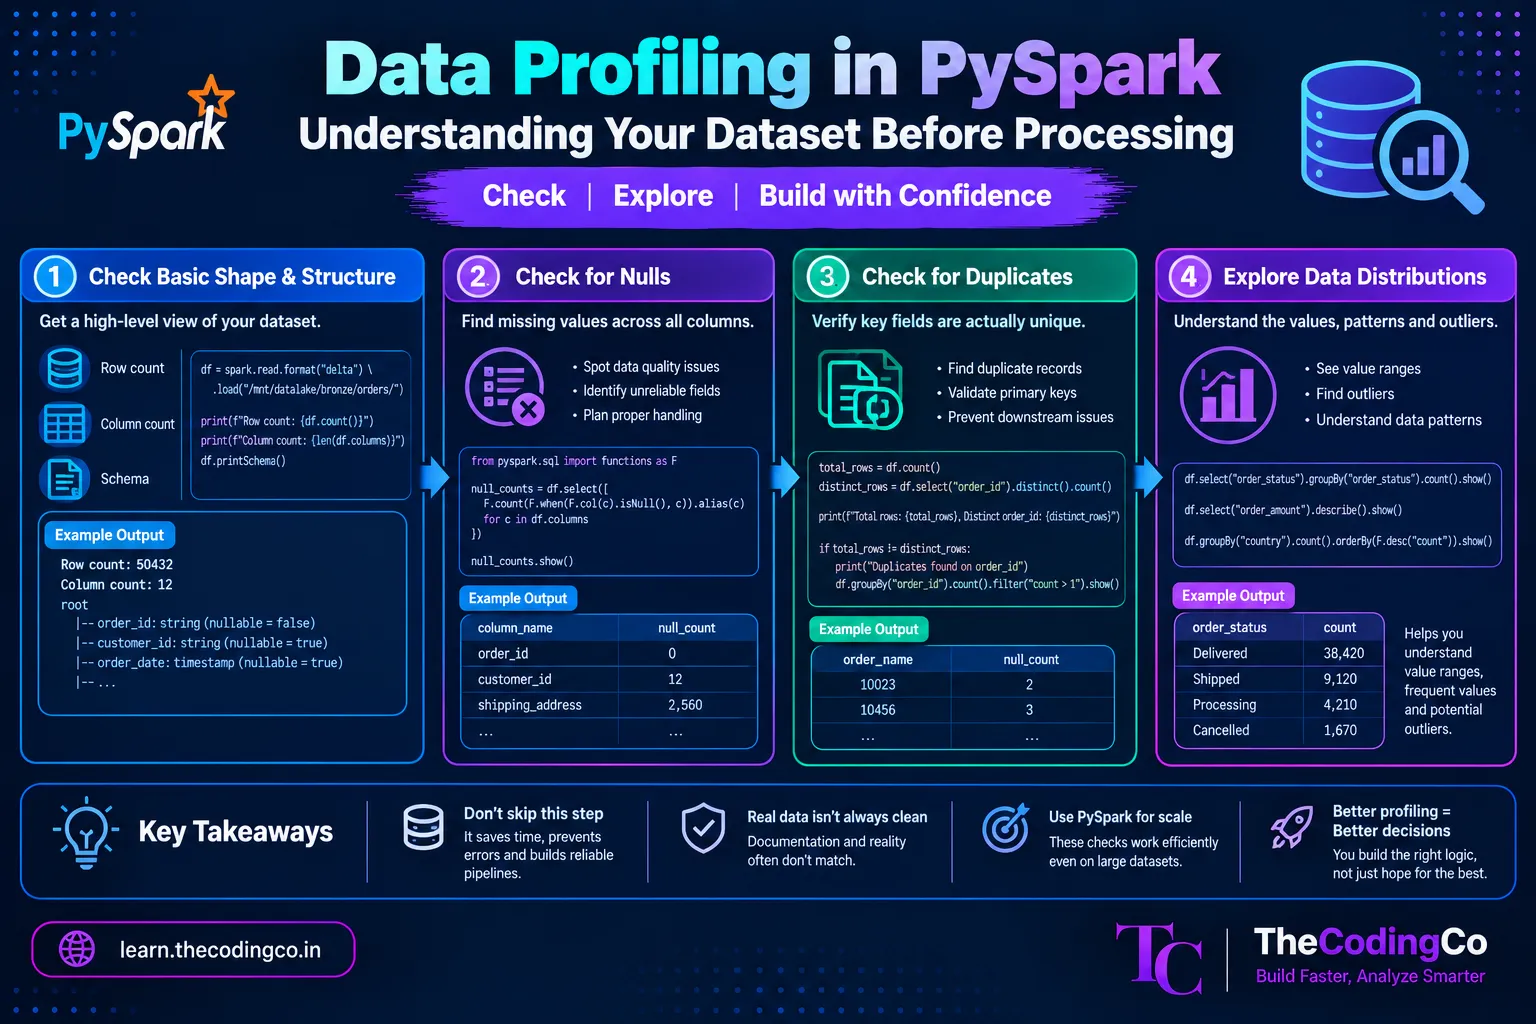
Starting with basic shape and structure
Before anything else, get a feel for the basic dimensions of the dataset you are working with.
df = spark.read.format("delta").load("/mnt/datalake/bronze/orders/")

print(f"Row count: {df.count()}")
print(f"Column count: {len(df.columns)}")

df.printSchema()
This sounds almost too basic to mention, but row count alone catches real problems. If you expected roughly fifty thousand new orders today and the count comes back at four hundred, something upstream likely failed silently, and you want to know that before building anything on top of this data, not after.
Checking for nulls across every column
Missing values are one of the most common sources of downstream problems, and checking for them systematically across the whole dataset, rather than assuming based on documentation, is worth doing early.
from pyspark.sql import functions as F

null_counts = df.select([
    F.count(F.when(F.col(c).isNull(), c)).alias(c)
    for c in df.columns
])

null_counts.show()
This gives you a null count for every column in one pass. Seeing that customer_id has zero nulls but shipping_address has a meaningful percentage of nulls tells you something concrete about how reliable this field actually is, which directly affects how you should handle it downstream, whether that means filtering, imputing a default, or flagging incomplete records rather than silently dropping them.
Checking for duplicates
Duplicate records are another common surprise, and checking for them directly, rather than assuming a source system's primary key is genuinely unique, saves a lot of confusion later.
total_rows = df.count()
distinct_rows = df.select("order_id").distinct().count()

print(f"Total rows: {total_rows}, Distinct order_id: {distinct_rows}")

if total_rows != distinct_rows:
    print("Duplicates found on order_id")
    df.groupBy("order_id").count().filter("count > 1").show()
Finding that order_id, which is supposed to be a unique identifier, actually has a few hundred duplicate values, tells you that either something is genuinely wrong upstream, or that this key is not actually as unique as documented, and your pipeline needs deduplication logic somewhere before this data reaches a fact table.
Looking at actual value distributions
For categorical or low cardinality columns, looking at the actual distinct values and their frequency often reveals surprises that a schema definition alone would never show.
df.groupBy("order_status").count().orderBy(F.desc("count")).show()
This might reveal that order_status contains not just the expected values like "completed," "cancelled," and "pending," but also an unexpected value like "COMPLETED" in all capitals, or an empty string, both of which would silently break any downstream logic filtering specifically on the lowercase "completed" value. Catching this during profiling means fixing it deliberately, rather than discovering it weeks later when someone asks why a report is undercounting completed orders.
Checking numeric ranges for sanity
For numeric columns, basic summary statistics catch a surprising number of real data quality issues.
df.select("order_amount", "quantity").describe().show()
This gives you min, max, mean, and standard deviation for these columns in one call. Finding a minimum order_amount of negative fifty, when negative order amounts should not logically exist, is exactly the kind of thing that is easy to miss if you never actually look at the range of values, but obvious once you do.
Checking date ranges and formats
Date columns deserve their own specific check, since they cause a disproportionate amount of downstream pipeline problems when they are inconsistent.
df.select(
    F.min("order_date").alias("earliest_date"),
    F.max("order_date").alias("latest_date")
).show()
Seeing an earliest_date value of something like the year 1900, when the business has only existed since 2015, is a strong signal of a data quality issue, likely a default or placeholder date being used somewhere upstream when a real date was missing, rather than an actual historical record.
Putting this into a repeatable profiling routine
Rather than manually running these checks one at a time for every new dataset, it is worth wrapping the common ones into a simple reusable function, so profiling a new dataset becomes a quick, consistent step rather than something that gets skipped under time pressure.
def profile_dataframe(df, key_column=None):
    print(f"Row count: {df.count()}")
    print(f"Column count: {len(df.columns)}")

    print("\nNull counts per column:")
    df.select([
        F.count(F.when(F.col(c).isNull(), c)).alias(c)
        for c in df.columns
    ]).show()

    if key_column:
        total = df.count()
        distinct = df.select(key_column).distinct().count()
        print(f"\n{key_column}: total={total}, distinct={distinct}")

    print("\nNumeric summary:")
    numeric_cols = [f.name for f in df.schema.fields if str(f.dataType) in ("IntegerType", "DoubleType", "LongType", "DecimalType(10,2)")]
    if numeric_cols:
        df.select(numeric_cols).describe().show()

profile_dataframe(df, key_column="order_id")
Having something like this ready to run against any new dataset, or any dataset you have not looked closely at in a while, turns profiling from an occasional afterthought into a quick, habitual first step.
Where this fits in a real pipeline
Profiling is not usually something you run as part of a scheduled production pipeline itself, since it is mostly a manual investigative step. It typically happens once, early on, when you are first building a pipeline for a new data source, or whenever you are debugging an unexpected downstream issue and need to understand what is actually going on in the raw data before deciding how to fix it.
That said, some of these same checks, particularly null counts on critical columns and basic row count sanity checks, do get built into ongoing automated data quality checks that run as part of the actual pipeline, which is a related but distinct topic from the one time investigative profiling covered here.
Interview angle
If asked how you approach a new dataset you have never worked with before, describing this kind of systematic profiling process, checking row counts, nulls, duplicates, value distributions, and ranges, shows a methodical approach rather than jumping straight into writing transformation code based on assumptions. If asked to give a specific example, mentioning something concrete like catching inconsistent casing in a status column, or an unexpected negative value in an amount column, demonstrates that this is a practiced habit rather than a theoretical answer.
Quick recap
Data profiling means actually looking at a new dataset closely before building transformation logic around it, checking basic row and column counts, null percentages across every column, duplicate values on expected unique keys, actual value distributions for categorical columns, and sanity checks on numeric ranges and date ranges. This step catches real discrepancies between what a source system's documentation claims and what the data actually contains, and doing it early prevents a lot of quiet, hard to trace problems from showing up much later in production.